How to Filter LangChain Agent Input Before the LLM
Don't pay tokens to reject tokens.
- The chain tokenizes whatever lands — duplicates, bursts and junk included.
- LLM-classifying input inside the chain means paying tokens to reject tokens.
- Filtering in front invokes the chain once per real event.
The problem
- A LangChain agent runs the model on whatever lands in its input.
- Duplicates, bursts and bot junk all get tokenized — and you pay for all of it.
- Guard inside the chain with an LLM and you pay tokens to reject tokens.
The solution
Two places to act, and they cost very differently:
- Inside the chain: a guard node saves the model call — but the handler already ran, and a burst still invokes it per fragment.
- In front of the endpoint: the chain never invokes, so nothing tokenizes.
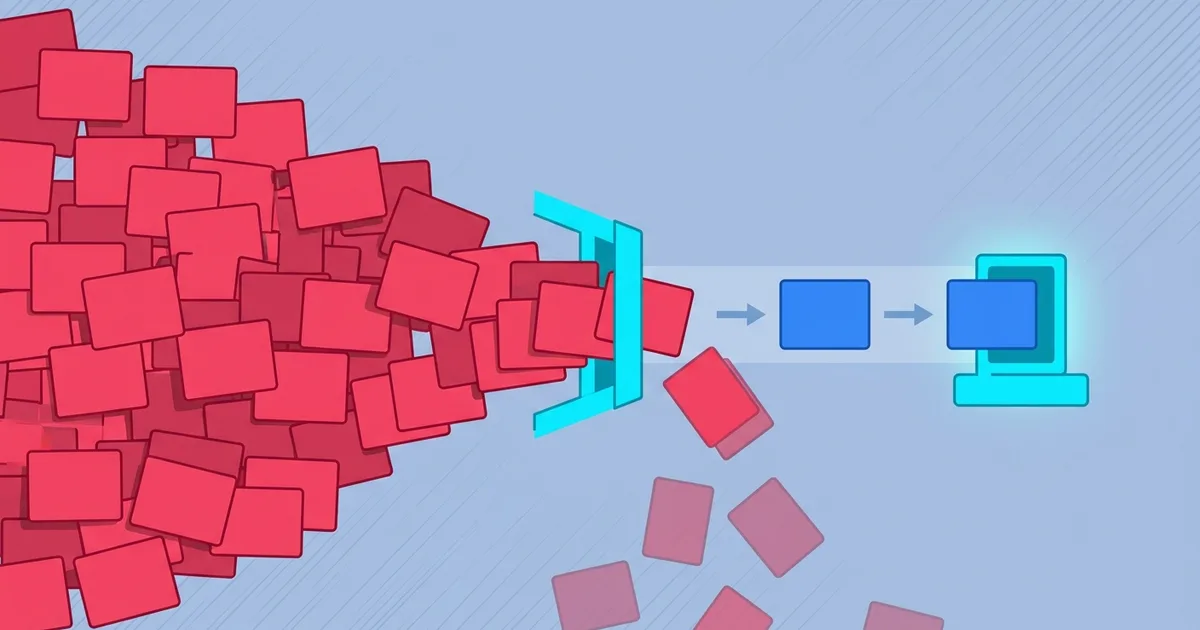
Drop duplicate retries, merge bursts into one invocation, reject junk and oversized payloads.
Result: the chain runs once per real event and your tokens track actual conversations.
Your LangChain agent runs the model on whatever lands in its input. A duplicate retry, a user who splits one thought across five messages, a bot probing your endpoint — the chain tokenizes all of it and you pay for all of it. The cheapest tokens are the ones the model never sees. Here is how to filter LangChain agent input before it reaches the LLM.
Why the chain is the wrong place to filter
Three patterns inflate the bill before any logic of yours runs: duplicates (senders retry on timeout, each a full chain invocation), bursts (a user types four messages — four invocations for one intent), and junk and abuse (bots, scanners, and oversized payloads the model tokenizes before you notice). None of it shows as an error, only as a token graph running ahead of your real conversations.
The manual fix (Option 1)
Guard inside the chain. Add a RunnableBranch or a plain validation function at the top of your chain: reject empty input, drop payloads over a size cap, and short-circuit before the expensive ChatModel call.
On a gateway, duplicates, bursts and junk are dropped before your endpoint is hit at all.
The catch: the handler ran before your guard
A pure-code guard saves the model call, but the request still ran your handler, a burst still invokes it per fragment, and you repeat the guard in every chain you expose. To stop the invocation itself, the filter has to live in front of the endpoint.
Place a gateway layer (Option 2) — faster
A message gateway sits between the sender and your webhook URL. You point senders at the gateway, and it drops duplicate retries, merges a burst into one message, and rejects junk before forwarding. Your FastAPI (or LangServe) endpoint receives one clean payload per real event, so the chain invokes once and your tokens track actual conversations.
Option 1 (in-chain) vs Option 2 (in front)
| Guard inside the chain | Filter in front (gateway) | |
|---|---|---|
| Duplicate retry | ~Handler still runs | ✓Chain never invoked |
| Burst of fragments | ~One invocation each | ✓Merged into one |
| Bot / oversized junk | ✕Tokenized if LLM-classified | ✓Rejected at the edge |
| Token-flood payload | ~Truncate after arrival | ✓Capped before forwarding |
| Every chain / endpoint | ~Repeat the guard each time | ✓One layer, all of them |
| Control of internals | ✓Full | ~Abstracted away |
A single oversized message is its own problem — see token floods and your agent’s budget. Usually duplicates and bursts waste the most; deduplicating and merging fragments cut the count with no change to your chain. It’s one piece of message quality for AI agents.
If option 2 sounds more like you, here’s the short version of how to set it up: keep junk out of your chain invocations →.
Either way — go make your chain run only on real input.
Thanks for reading. 👋
Orlando. -
Orlando Quijada
Technologist with 15+ years of experience. Developer, SaaS tester, and AI collaboration & optimization specialist. Currently contributing at portarus.com.
Written on